Skip to content

Open nowPosted 54 days ago

Senior Databricks / Azure Data Lake Engineer

Proclink43 open roles

Where
Hyderabad
Get the CV for this job

From $25 per CV, paid once. No subscription.

Your applicationOpen nowSenior Databricks / Azure Data Lake EngineerProclink · Hyderabad
  1. YouYes, apply to this one.

  2. CV RocketCV written for this posting.

  3. 25 readersRecruiter, hiring manager, skeptic. Round after round.

  4. CV RocketApplied on Proclink's own form.

The reply lands in your private mailbox

3×more interviews than doing it yourself with ChatGPT.

The clock on this job

Early applications get read.

12.1% of postings close within 7 days. Measured by our own scanner across the market.

Share of postings closed within
  1. 2.1%1 day
  2. 4.5%3 days
  3. 12.1%7 days
  4. 19.1%14 days
  5. 35.6%30 days
  6. 52.7%60 days
This job: posted 54 days ago

The posting

Position

Senior Databricks / Azure Data Lake Engineer

Experience

6+ Years

Location

Hyderabad, Telangana

Employment Type

Full-Time

Role Overview

We are looking for an experienced Senior Databricks / Azure Data Lake Engineer with 6+ years of experience in designing, developing, implementing and supporting scalable data engineering solutions on Microsoft Azure.

The candidate will be responsible for building robust data pipelines, data lake architectures and transformation frameworks using Azure Databricks, Azure Data Lake Storage (ADLS Gen2), PySpark and SQL.

The role requires close collaboration with Data Engineering, Application Engineering, Business Intelligence, Architecture, DevOps and Data Governance teams to deliver secure, scalable and high-quality data solutions.

The ideal candidate should have strong hands-on experience with Databricks, Delta Lake, PySpark, Azure Data Lake and Azure data services, along with good understanding of data architecture and performance optimisation.

Key Responsibilities

Azure Databricks

Design, develop and maintain scalable data engineering solutions using Azure Databricks.

Develop PySpark notebooks and production-grade data processing jobs.

Build reusable frameworks for batch and incremental data processing.

Configure and optimise Databricks clusters and compute resources.

Implement appropriate cluster policies, job configurations and access controls.

Troubleshoot Databricks jobs, performance issues and production failures.

Implement Databricks Workflows/Jobs for scheduling and orchestration.

Azure Data Lake

Design and manage data solutions using Azure Data Lake Storage Gen2 (ADLS).

Implement appropriate data lake folder structures and data organisation strategies.

Develop ingestion frameworks for structured and semi-structured data.

Implement incremental, full-load and CDC-based ingestion patterns.

Work with data formats such as:

Parquet

Delta

JSON

CSV

Avro

Implement data partitioning and lifecycle strategies.

Ensure data quality, availability and reliability across data lake environments.

Delta Lake

Strong understanding of Delta Lake architecture and capabilities.

Implement ACID-compliant data processing using Delta tables.

Work with:

MERGE

UPDATE

DELETE

Time Travel

Schema Evolution

Optimistic Concurrency

Implement incremental processing and CDC pipelines.

Optimise Delta tables using appropriate partitioning and optimisation techniques.

Troubleshoot data consistency and performance issues.

PySpark & Data Engineering

Develop scalable data transformation pipelines using PySpark.

Write efficient Spark SQL and DataFrame transformations.

Optimise Spark jobs for large-volume datasets.

Analyse and resolve:

Data skew

Shuffle issues

Partitioning problems

Memory issues

Long-running jobs

Implement appropriate caching, repartitioning and broadcast strategies.

Develop reusable PySpark libraries and frameworks.

Perform data validation and reconciliation across source and target systems.

Data Ingestion & Integration

Build data pipelines integrating data from multiple sources, including:

REST APIs

Relational databases

Kafka

Files

Cloud storage

Enterprise applications

Implement batch and near-real-time data ingestion.

Work with CDC technologies and incremental data processing.

Design resilient ingestion frameworks with appropriate error handling and retry mechanisms.

Azure Data Services

Hands-on experience with relevant Azure services such as:

Azure Data Lake Storage Gen2

Azure Databricks

Azure Data Factory

Azure Key Vault

Azure Synapse Analytics

Azure Event Hubs

Azure Monitor

Microsoft Entra ID

Experience integrating these services into enterprise data platforms is highly desirable.

Azure Data Factory / Orchestration

Develop and maintain Azure Data Factory pipelines.

Implement pipeline orchestration between ADF and Databricks.

Develop parameterised and reusable pipelines.

Implement dependency management and error handling.

Configure monitoring, alerts and retry mechanisms.

Manage production scheduling and operational support.

Data Quality & Governance

Implement data validation and reconciliation frameworks.

Identify and resolve data quality issues.

Implement data quality checks at ingestion and transformation stages.

Follow enterprise data governance and security standards.

Maintain metadata, data lineage and technical documentation.

Implement appropriate access controls and data protection mechanisms.

Performance Optimisation

Analyse and optimise Databricks/Spark workloads.

Optimise SQL queries and data transformations.

Tune Spark configurations and cluster sizing.

Identify bottlenecks in data pipelines.

Optimise storage and compute costs.

Implement appropriate partitioning, caching and file-size management strategies.

CI/CD & DevOps

Integrate Databricks development with CI/CD pipelines.

Experience with Azure DevOps and/or GitHub Actions.

Implement source control for notebooks, code and configuration.

Automate deployment across:

Development → QA → UAT → Production

Implement environment-specific configuration management.

Follow enterprise release and change-management processes.

Security

Implement secure access to Azure Data Lake and Databricks.

Strong understanding of Azure RBAC and Microsoft Entra ID.

Manage secrets using Azure Key Vault.

Implement secure service-to-service authentication.

Follow enterprise security and compliance requirements.

Experience with Databricks access controls and Unity Catalog is highly desirable.

Production Support

Provide L2/L3 support for production data pipelines.

Monitor scheduled jobs and resolve failures within agreed SLAs.

Perform root-cause analysis for production incidents.

Implement permanent fixes and preventive actions.

Participate in on-call/support rotations where required.

Maintain operational runbooks and technical documentation.

Required Technical Skills

Must Have

6+ years of experience in Data Engineering.

Strong hands-on experience with Azure Databricks.

Strong expertise in PySpark.

Strong SQL skills.

Hands-on experience with Azure Data Lake Storage Gen2.

Strong understanding of Delta Lake.

Experience developing large-scale ETL/ELT pipelines.

Experience with Azure Data Factory.

Experience with batch and incremental data processing.

Experience with data partitioning and performance optimisation.

Strong understanding of data engineering principles.

Experience with Git and CI/CD.

Experience supporting production data platforms.

Good to Have

Databricks certification.

Unity Catalog experience.

Azure Synapse experience.

Kafka / Event Hubs experience.

CDC implementation experience.

Azure DevOps / GitHub Actions.

Terraform / Infrastructure as Code.

Python development experience.

Experience with data governance and lineage.

Experience in FinTech / Banking / Financial Services.

Experience handling large-scale transactional datasets.

Preferred Technical Stack

Cloud : Microsoft Azure

Data Platform : Azure Databricks

Data Lake : ADLS Gen2

Processing : Apache Spark / PySpark

Storage Format : Delta Lake / Parquet

Orchestration : Azure Data Factory / Databricks Workflows

Database : SQL Server / PostgreSQL / Azure SQL / Synapse

Streaming : Kafka / Azure Event Hubs

Security : Entra ID / RBAC / Key Vault

CI/CD : Azure DevOps / GitHub Actions

IaC : Terraform

Source Control : Git

Key Deliverables

The successful candidate will be expected to:

Build highly scalable and reliable Azure data pipelines.

Develop reusable Databricks/PySpark frameworks.

Improve data pipeline performance and reliability.

Implement robust data quality and reconciliation mechanisms.

Reduce pipeline processing time and cloud infrastructure costs.

Maintain high availability of production data pipelines.

Ensure compliance with enterprise security and governance standards.

Improve automation across data engineering processes.

Maintain high-quality technical documentation.

Collaborate effectively with architects, developers, analysts and business stakeholders.

Experience in Large-Scale Data Platforms

Candidates should ideally have experience working with:

Large-volume transactional data.

Multiple source systems.

Complex ETL/ELT pipelines.

Batch and near-real-time processing.

Production-critical data platforms.

Multiple development teams and distributed engineering teams.

Enterprise data governance and security standards.

Soft Skills

Strong analytical and problem-solving skills.

Excellent communication and collaboration skills.

Ability to work with cross-functional engineering teams.

Strong ownership of production systems.

Ability to troubleshoot complex data and performance problems.

Good understanding of software engineering best practices.

Strong documentation and knowledge-sharing capabilities.

Ability to mentor junior and mid-level data engineers.

Education

Bachelor's or Master's degree in Computer Science, Information Technology, Engineering, Data Science or a related discipline.

From $25, paid onceGet the CV for this job

What happens when you press

One press. We do the rest.

  1. A CV for this posting

    Written against Proclink's own wording, from every piece of relevant proof in your profile.

  2. 25 readers review it

    Recruiter, hiring manager, skeptic and more read every draft, round after round. You get the best round.
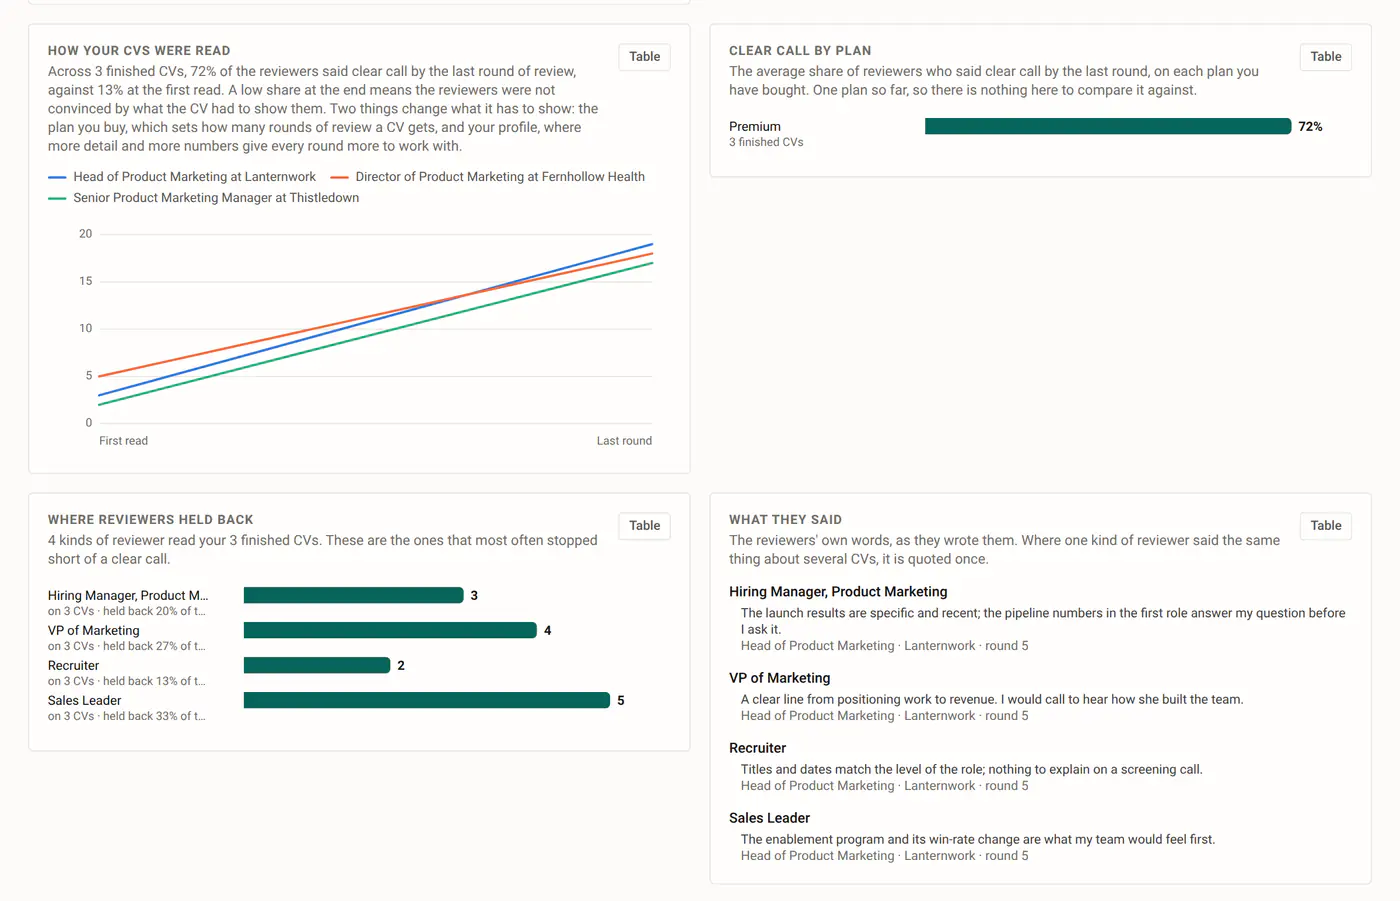
    The review screen in CV Rocket: how each CV was read, round by round.
  3. We apply on Proclink's form

    Our application engine gets through the hardest forms there are. Where a question needs you, AI suggests the best answer. Don't want us applying from our IP addresses? Use our Chrome extension: we apply straight from your own browser.
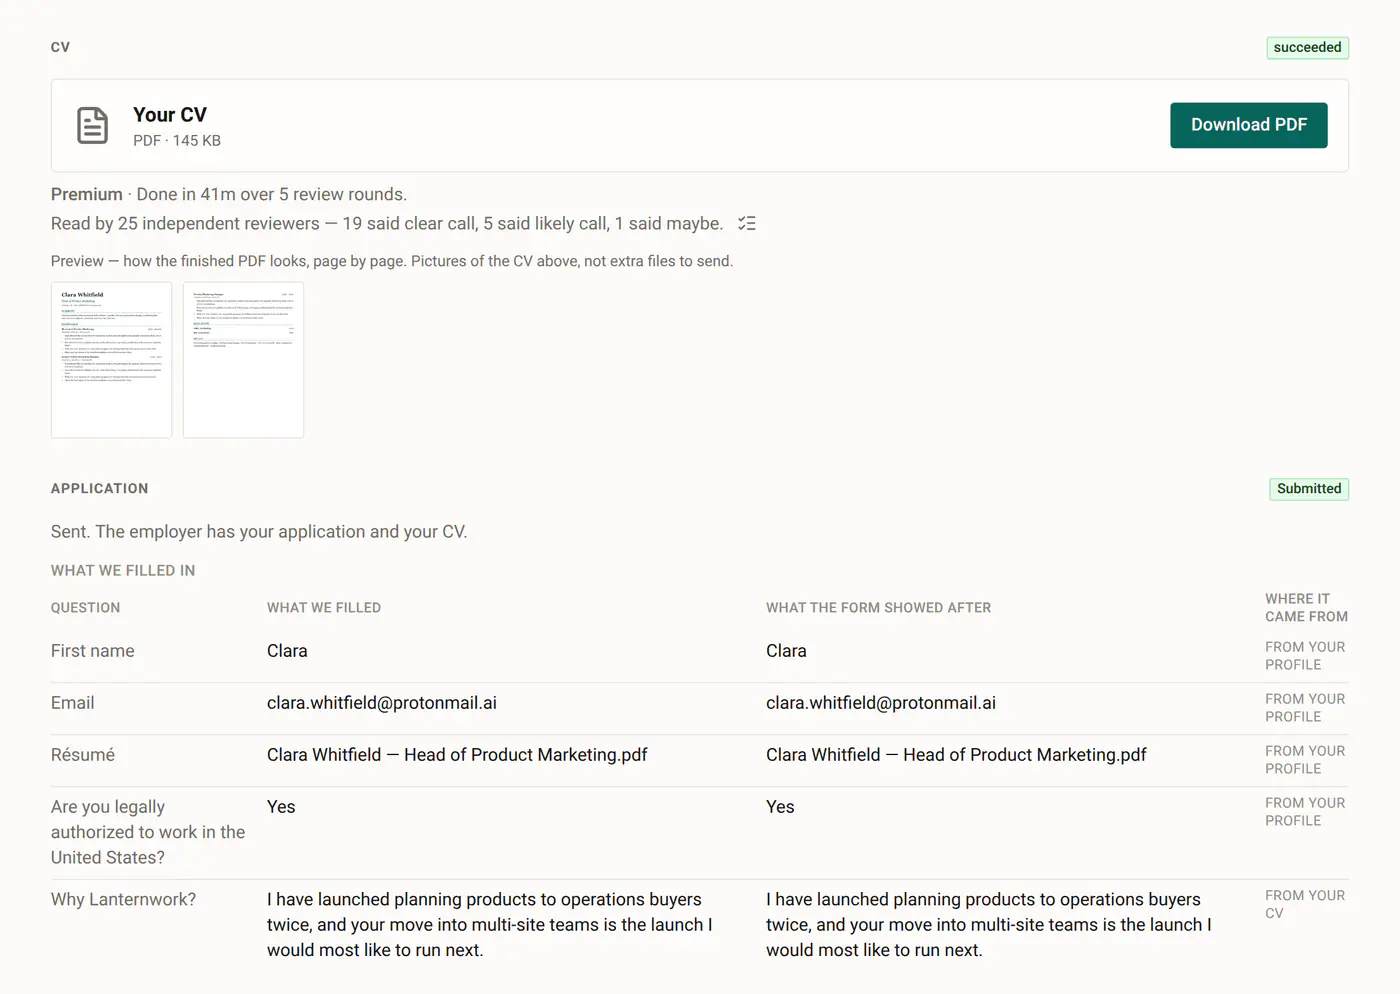
    An application in CV Rocket: every answer filled in on the employer's form.
  4. Every reply, sorted

    Proclink's answer lands in your private mailbox, and we classify it on arrival: interview, question, rejection.
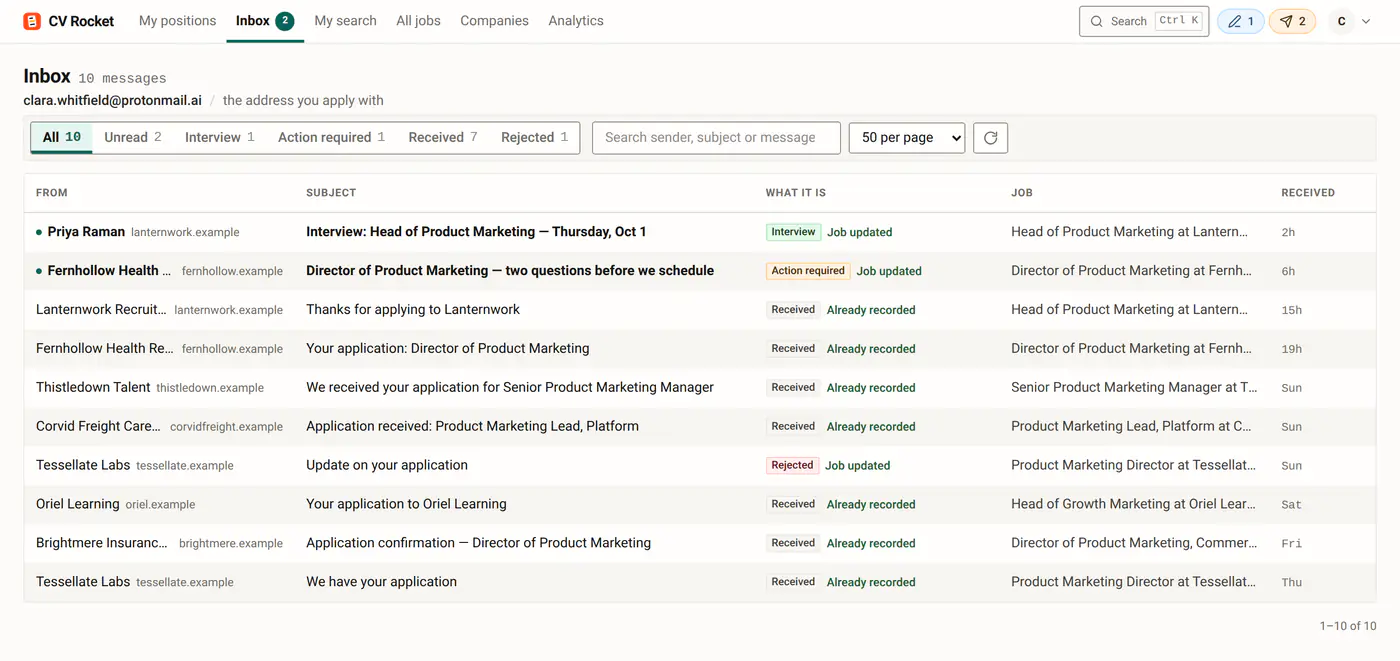
    The CV Rocket inbox: each employer reply classified as an interview, an action or a rejection.
  5. Reply with AI

    AI helps you write the email, checks it and sends it. We show you whether the recruiter read it.

  6. The interview in your calendar

    Full integration with your calendar. The invitation goes straight in.
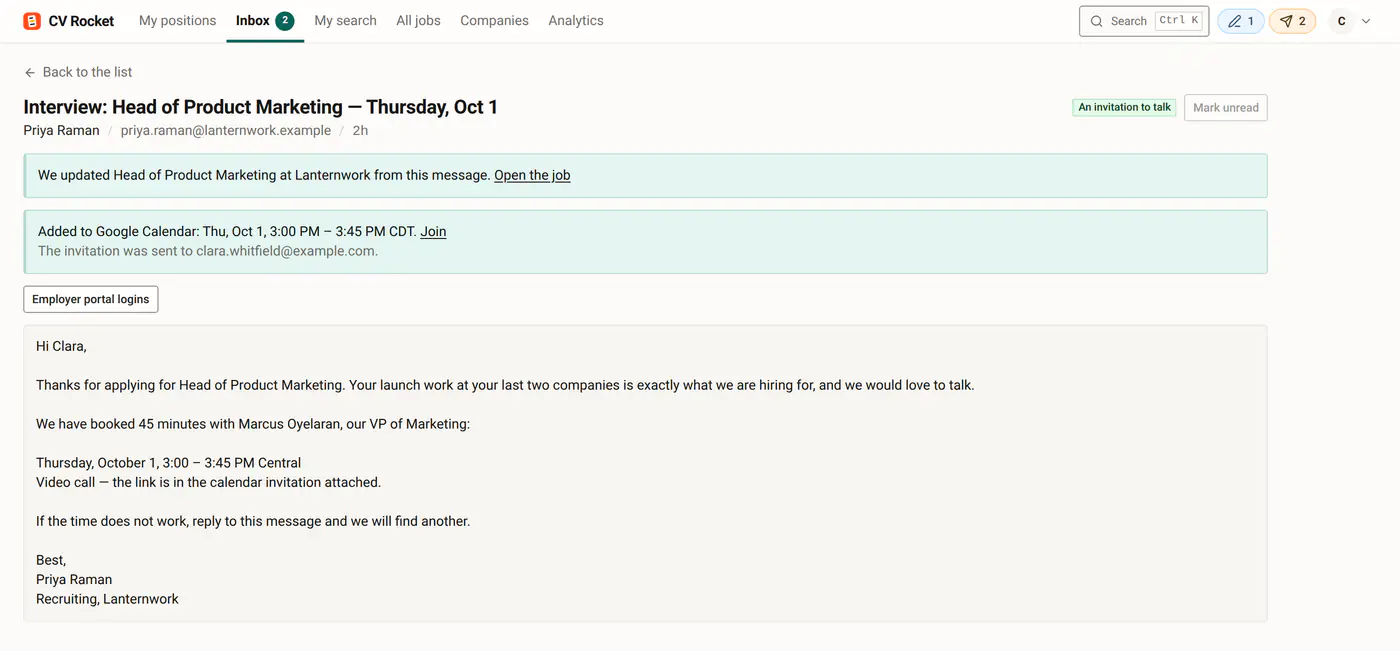
    An interview invitation in the CV Rocket inbox, added to the candidate's calendar.
Get the CV for this job

From $25 per CV, paid once. No subscription.

Why it works

3×

more interviews than doing it yourself with ChatGPT.

ChatGPT writes a CV and never learns what happened to it. We see every reply. For each CV we know:

  • How it was written, and how the review scored it
  • When we applied, and how long after the posting went up
  • Which posting, which company, which city
  • Who got the interview, and who heard nothing

That is how we know which CVs get called.

Get the CV for this job

From $25 per CV, paid once. No subscription.

The numbers game

More applications. More interviews.

Every application goes out with its own CV, written for that posting and paid once. Send enough of them and the law of large numbers finds you the job.

By hand5–10
With CV Rocket100
applications a day

Nearby

Live postings like this one

Same employer first, then the same role elsewhere.

Before you press

Straight answers

Get the CV for this job

From $25 per CV, paid once. No subscription.

What if my background isn't good enough?

We make the most of the background you have. The CV uses every piece of relevant proof your profile holds, and one of the 25 readers reads your whole profile and flags what the CV left out.

Do you really apply for me?

Yes, on the employer's own form, the hardest ones included. Where a question needs you, you answer it right there and AI suggests the best answer. Don't want us applying from our IP addresses? Use our Chrome extension: we apply straight from your own browser.

Is it a subscription?

No. You pay once per CV, from $25. Every application goes out with its own CV, written for that posting.

One job. One CV.
Paid once.

Pick the posting you want. We write for it, apply for you and catch the reply.

Get the CV for this job

From $25 per CV, paid once. No subscription.